Journal of Emerging InvestigatorsAcceptedIn press
Training and comparison of fine-tuned small language models as math tutoring assistants
Journal of Emerging Investigators (JEI), 2026 (in press)
TL;DR
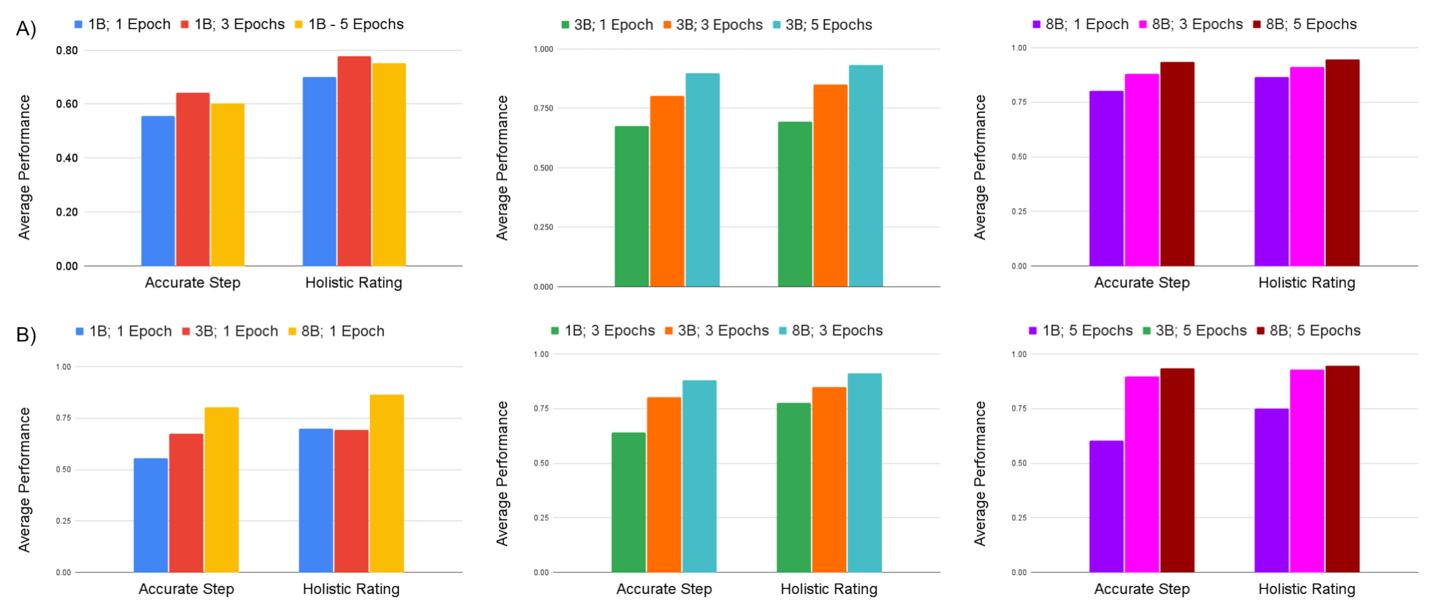
Across nine fine-tuned Llama math tutors (1B, 3B and 8B parameters, 1 to 5 training epochs), parameter count mattered more than training time; the 8B model trained for five epochs gave a correct first step 93.65% of the time.
Abstract
Recent breakthroughs in artificial intelligence (AI) have revolutionized not only computer science but also automation, enabling machines to perform tasks only humans could once do. AI tutoring assistants can support math education by providing step-by-step guidance, but their effectiveness depends substantially on model size and training duration. However, large language models require a very significant number of resources, making them impractical for schools. This study evaluates Llama 3.2 configurations with 1 billion (1B), 3 billion (3B), and 8 billion (8B) parameters, trained for 1, 3, or 5 epochs, as tutoring tools for elementary, middle, and high school math. We hypothesized that increasing a Llama 3.2 model’s parameter count would improve step-accuracy more effectively than increasing the number of epochs during fine-tuning. Using Google Colab and Unsloth’s open-source code, we fine-tuned the models on 538 math queries. We assessed performance on 126 test prompts based on their ability to avoid revealing answers, provide accurate step-by-step hints and guidance, and achieve high human-rated quality. The 8B model at 5 epochs performed best (93.65% accuracy, 0.946 rating), while the 1B model at 1 epoch lagged in performance (55.56% accuracy, 0.700 rating). These results suggest that small, fine-tuned language models can provide a practical balance between educational quality and efficiency while mitigating cost, making them viable as AI tutors for classrooms.
Keywords
small language models · math tutor · fine-tuning · training epochs · parameter scaling · Llama 3.2 · artificial intelligence · machine learning